#Roadmap
Design rationale, not a plan of record. Each section takes one part of Ambit and says what it decided, why, and whether it is built; what each part still lacks is collected in the status table. Nothing here has a date or an owner. Work that is going to be built belongs in an issue, where it can be assigned and closed.
Ambit reads your configuration, places it on a curated tech tree, and answers questions about the structure: what is reached, what the next step is, what would break if a given thing disappeared. That is a model of what exists. The sections below extend it to a model of what can be acquired, verified and authorized, and close the loop between the two, and most of that is built.
Ambit takes its name from the Latin ambitus: circuit, perimeter, sphere of action. In Roman law and modern governance alike, an ambit is the boundary within which authority is legitimate and outside of which power is unauthorized or invalid. An agent without an ambit is either reckless (executing until an unhandled permission error crashes the session) or paralyzed (asking for confirmation on every keystroke). Ambit is the dynamic, verifiable model of that perimeter: what the human-agent system can reliably do right now, what it is authorized to do autonomously, and how that perimeter safely expands over time.
The deep dive is the reference for the built parts, so a built section here keeps its rationale and does not repeat the reference. Sections are ordered by dependency, not by date.
#The argument
A capability is not something configured. A capability is an action the system has evidence it can perform.
Everything here follows from taking that seriously. It is the first half of the claim the ideas page states whole: what an agent setup can do is not written in any config file, because it is composed, it has to be verified, and it differs from what the setup is allowed to do.
That claim gives four layers, ordered by ambition. Each is defensible on its own; each depends on the one above it.
| Layer | What it does |
|---|---|
| 1 · Inventory | discover the capabilities implicit in configuration and infrastructure, model their dependencies, costs, and failure cascades |
| 2 · Assurance | distinguish configured from demonstrated: installed ≠ working ≠ authorized |
| 3 · Planning | given a desired outcome, compute the capability delta and compare paths that close it |
| 4 · Reflexive infrastructure | agents use the model to improve the environment they themselves operate in |
Layer 4 is called "reflexive infrastructure", not "self-improving", because the system can inspect the conditions of its own action and propose modifications to them, and a human approves every one.
All four serve a different objective function. A conventional assistant optimizes roughly:
utility = task_value − cost − risk
Ambit adds a fourth term and takes it seriously:
utility = task_value − cost − risk + λ · reusable_capability_created
That single change produces the behaviors worth having:
- "I can do this by hand in 20 minutes, but 35 minutes spent building it as a capability makes every future instance nearly free."
- "Don't add another service — the Postgres node already does this with pgvector."
- "We have done this manually five times. It should be a skill."
- "This mini PC closes four current bottlenecks at once."
The objective is not a bigger graph. It is:
Increase the frontier of reliably achievable goals per unit of human attention, money, risk, and infrastructure.
And the loop that objective runs on:
do real work → discover friction → identify the capability deficit
     ↑                                        │
     │                              find the cheapest reusable fix
     │                                        │
     │                              human + agent decide
     │                                        │
     │                              build / connect / acquire
     │                                        │
     │                              verify it
     │                                        │
     └──────── more becomes possible ◄── record it in the graph
#Status at a glance
| § | Section | Status | What remains |
|---|---|---|---|
| 1 | Separate capability from implementation | built | Rationalized into adapters, upstreams, models and substrates. resource disambiguated into physical substrates and remote upstreams; bound affordances map actions to concrete target objects (§13.9, §18). |
| 2 | Put the human and the machines in the graph | partly built | Cost and risk tolerance are not modeled: a preference is a word matched to an alternative's properties, not a budget or a threshold, so a plan cannot say this step is not worth your attention or you asked not to spend more than this. A device or service is probed only when someone types ambit incidents, so nothing notices one stop answering between runs. What ambit graph capacity reads from the tailnet and this machine's memory is printed and never seeded. |
| 3 | Acquisition recipes | partly built | A recipe's multi-step verification is not executable: a check is one read-only command, not a procedure with an undo. |
| 4 | Detection becomes verification | built, and gates | Decoupled into orthogonal state (reachability) and assurance (empirical evidence). The semantic inversion of degraded is cured by recovering; raw check outcomes are binary (passed/failed) while node lifecycles reflect assurance levels (proven, reliable, recovering). |
| 5 | Goal → capability delta | partly built | A goal naming no known vocabulary gets at most a suggested existing node (--judge): maintain the homelab unattended reaches three known capabilities, and nothing synthesizes service health observation or bounded restart authority out of whole cloth. Whole-strategy alternatives (broad authority, a capability-scoped MCP, a kubernetes migration) have to be authored before a goal can be offered as a choice at that grain. |
| 6 | Failure becomes an input | built | Recurrence becoming a proposal (§5, §10) is still a human step, deliberately: ambit next ranks the recurrences and drafts nothing until someone chooses. |
| 7 | The ledger | shipped | Use carries no object, so which capability was exercised on what is unanswered (§13.9). The Claude Code plugin records an ask and not its answer, since no hook says how a person replied, and the OpenCode plugin does the same under OpenCode 1, so those asks are drawn as points (L1). Both plugins time a use between the hooks before and after it, except a call someone was asked to approve, whose span holds the person's wait, and the control plane still writes a fixed value. Cursor feeds it through its hooks (ambit connect cursor --ledger), without tokens, since its hooks report none. Claude Code's transcripts, and the session logs Codex, OpenCode and Amp keep, give token counts per hour as they grow, with nothing installed, but not tool runs or asks; other runtimes have no bridge of their own. |
| 7b | Affordance domains | built, derived | The derived domains have no column on the map, deliberately: the era grammar is designed, and adding columns for what ambit graph affordances computes would be design work, not model work. The theory's environment term, an affordance holding in one workspace and not another, has no representation. |
| 8 | A runtime adapter layer | partly built | No runtime publishes a capability surface yet, so file-parsing is the path that runs. An IDE sidebar extension embedding the AG-UI stream is unbuilt. |
| 9 | Authority as a first-class edge | built, and mediates one thing | The 6-rung Supervisory Ladder formalizes authority from ungranted to autonomous, harmonizing runtime gate verdicts (ALLOW/CHALLENGE/DENY) with progressive promotion on evidence. |
| 9b | The record it writes: STD-07 | shipped | No system outside Ambit is declared as reading its stream: downstream in server.json is empty. action and outcome records wait on a real environment adapter (§15). |
| 10 | A second-generation MCP | partly built | A capability with no declared check applies unverified and reports that it did; refusing outright would break the acquisition path for every capability whose recipe is not a check, so it stays a report until §3's multi-step verification can back it. No MCP tool applies or rolls back a change. Stdio is the only transport; HTTP/SSE and WebSocket transports, sandboxed container/WASM execution, an authenticated CLI installer (ambit install) and an outputSchema per tool are unbuilt. |
| 11 | The visualizer becomes a negotiating surface | built and shipping | AG-UI's tool-call and reasoning events are not emitted, by design. A light theme is unbuilt. The whole-map export draws the standard lens only, since the Attention and Authority lenses show who stepped in and what may act without asking. |
| 12 | The long-running agent | built | Nothing in this section's scope. By design, a reply to a dispatched proposal comes back through ambit approve on a machine holding the key, never through the channel it was pushed to. |
| 13 | Expanding the ambit | built | The era tree does not refer to objects: read repo A and read repo B are two recorded facts and still one node. |
| 14 | The economic half | partly built | Human agency accounting normalized into Compensatory Friction (mechanical shims and glue to automate away) versus Sovereign Discretion (judgment, ethics and fiduciary sign-off to preserve). Spend recorded from session logs against declared prices. |
| 15 | The control plane | built, against a simulated environment | A runtime that routes through the proxy by default: it has its own entry point and no ambit verb, so nothing reaches it unless a caller chooses to. The Docker adapter, chosen explicitly, runs an approved step in an isolated container and deploys nothing anywhere; an adapter for a real deploy target (Kubernetes, a deploy API) is unbuilt. |
| 16 | Federation, fleet governance, and team agency | partly built | Multi-tenant graph synchronization, GitOps PR-driven governance, enterprise role-based access control, and compliance audit exports (SOC2) are unbuilt. Only delegation records are hash-chained, and a machine's last-seen time moves only when ambit incidents runs. |
| 17 | Defined outcomes | proposed, unbuilt | Versioned scenario definitions, attempts bound to their actual targets and setup, acceptance evidence, and comparisons across environments. Work runs, recorded outcomes, scoped authority and node checks supply parts of the foundation. |
| 18 | Ontological rationalization | built and normalized | Decoupled assurance from reachability; disambiguated provider collisions; unified 6-rung supervisory ladder; formal bound affordance calculus; normalized labor accounting (compensatory friction vs sovereign discretion). |
#1. Separate capability from implementation — built
A node can conflate two things: the capability (web research) and the thing providing it (a Tavily MCP server). Splitting them was the prerequisite for almost everything else, because it lets a capability survive a change of provider and lets two providers compete to satisfy one need.
Six first-class object types:
| Object | Example |
|---|---|
| Goal | "agents maintain my homelab unattended" |
| Capability | restart a service |
| Provider | Proxmox MCP |
| Resource | the NUC that runs Proxmox |
| Authority | may restart containers, not hosts |
| Evidence | probe restarted a test container and confirmed health |
Goal  "autonomously maintain homelab"
  │ requires
  ▼
Capability  "diagnose service failure"
  │ provided_by
  ├──────────────┐
  ▼              ▼
Netdata MCP    SSH / shell
  │              │
  └─── runs_on ──┘
          ▼
     homelab node
Once providers are separate, the comparison stops being between capabilities and becomes one between ways of obtaining the same capability. That is the comparison that actually matters when deciding what to build, and it is what ambit goal --paths and ambit catalog do today.
Built. Every node declares what kind of thing it is (capability, action, provider, resource, actor, runtime) and every edge declares what the relation means. Of the six object types above, three are node kinds; authority and evidence are tables of their own, and goal became one when §14 needed to price a goal and not only route to it.
ambit impact asks whether anything else supplies a capability before calling its loss critical, so removing one of three git providers reports the capability as surviving on the other two. ambit status lists capabilities with exactly one provider, which is fragility; ambit_bottlenecks over MCP ranks leverage, which is the opposite reading. Edges are typed so that every analysis reads what a relation means from a column, never from how an adapter worded it.
Action-level capabilities are built. A tech-tree node may declare contract.can, and each entry becomes an act:<node>/<action> node conferred by the capability and carrying its own authority — so the model can now say may read the repository, may not merge to its default branch, which is the distinction the coarse node could not make. A node that declares no contract behaves exactly as before.
The id rework was deliberately avoided. Every id appears in the ledger's stored snapshots, so re-iding would invalidate the history of the one component whose value is that its history is continuous. Kind is a column instead, existing databases migrate by ALTER TABLE and a one-time backfill, and ambit status, ambit impact, ambit goal and ambit history return byte-identical output against a graph seeded by the previous version. The cost is that an id no longer tells you what it is, and callers must read the column.
Scope is checked now, not merely recorded. ambit authority scope <target> (repo:owner/name, device:nuc, svc:ollama) lists every authority grant, whether its scope covers the target, and the effective mode the covering grants resolve to. Scope is a prefix claim: repo:owner/name covers the repo and its branches, and a grant scoped elsewhere is named as excluded, never silently treated as covering. Scope decides as well as reporting: §9 gives the resolution rule, and §13.3 gives the grant that exercises it.
Also built: credential. Counted by provider, three things supplying one capability read as threefold redundancy, and if all three present the same token, one revocation takes them down together. A uses edge records what a provider authenticates with; ambit status lists such a capability among its spofs, ambit impact says it survives on one key, and ambit credentials answers what a revocation would end. What counts is the intersection, not the union: providers holding {A}, {A,B} and {B} survive losing either, and reporting that as fragile would be the same error inverted.
Credentials are declared, never inferred. A credentials block in the config names which providers share one, and ambit credentials and every shared-credential finding know only what such a block names. A credential node holds an identity and never a secret, since there is no field one could arrive in. It is excluded from the frontier by kind, because nothing provides a credential and a new node with no providers would otherwise count as a capability gained.
#2. Put the human and the machines in the graph — partly built
The interesting unit is not the agent. It is user + agent population + infrastructure, and each brings something the others cannot.
The human contributes authority, judgment, money, physical access, and the willingness to accept particular risks. Not as a profile — as an actor with capabilities and authorities, the same as any other node:
human:kanav
  provides: [approve-purchases, physical-machine-access, github-admin,
             evaluate-subjective-output]
  prefers:  [local-when-practical, minimize-recurring-cost,
             tolerate-setup-for-compounding-benefit]
Hardware stops being "some computers" and becomes addressable capacity: 24GB of always-on VRAM reachable over Tailscale is latent local inference, embeddings, browser workers, and batch evaluation — and the graph can then observe that you already own most of what private semantic search requires.
The payoff is that a plan can include the human as a step. Instead of "I can't do that", the answer becomes: eight of these ten steps are mine; you need to authorize the device and press the reset button; then I finish and verify the rest.
Built: an actors block seeds people as nodes. provides becomes a capability only that person supplies; authorizes becomes a hard prerequisite edge, so ambit goal continuous-delivery reports requires_person: Kanav and does not present the path as autonomous. Approval is a dependency, not a policy note.
Preferences are built. A person may declare how they like things done (prefers: [local-when-practical, minimize-recurring-cost]), stored as data and matched by ambit goal against the alternatives a step's acquisition actually offers. Where the plan's default choice fights a stated preference, the plan names it and points at the alternative that matches: asking Kanav to approve a hosted, recurring CI default when they prefer local and one-off reads as if there is no choice, and the plan refuses to read that way. ambit goal --prefs [who] lists the declarations.
Machines are now capability-bearing in the engine, not only in the visualizer. INFRA_MANIFEST devices seed as resource nodes with runs_on edges to the services hosted on them, so ambit impact device:nuc answers what actually breaks when the machine disappears, and a plan can point at capacity the graph can count.
Auto-probing is what keeps this honest. A static INFRA_MANIFEST is a reasonable seed, but machines change underneath it: containers crash, mesh networks drop routes, and memory fills. The server now reads the local Docker socket (DOCKER_HOST, /var/run/docker.sock, or the per-user socket a desktop runtime leaves) with one GET /containers/json, and every container lands in the infrastructure scan as a service on a device:docker node, running, paused or exited. No socket is a quiet absence; a socket file with a stopped engine behind it is a warning, not an error. ambit incidents probes each service the manifest gives a status URL, when typed, and opens an incident run for one that does not answer, with the gate already asked whether restarting it is permitted. ambit graph capacity reads the Tailscale daemon (tailscale status --json) and this machine's memory (unified memory on Apple silicon, nvidia-smi elsewhere), and names the online machines no manifest declares. It runs only when typed and writes nothing: a peer on the tailnet is not seeded as a device, since a machine being reachable says nothing about what it runs, and a peer's own memory cannot be read from here.
Every human act is recorded and counted. ambit attention measures how much of the work still runs through the person (approvals, applications, permission blocks, failed checks) and names the reducible ones: the same approval demanded repeatedly is a candidate for granting the authority once, reviewed before it widens. ambit notify <topic> pushes that digest to ntfy, and only when a topic is given — the attention loop is opt-in and local-first. The push is a single POST of the digest text. This is the first turn of "repeated demands on human effort become evidence about what the system should learn to do without the human."
#3. Acquisition recipes — partly built
The largest single addition to the data model. A node stops being documentation and becomes an installable competency:
capability: persistent-memory
contract:
  can: [store_fact, retrieve_fact, forget_fact]
requires: [durable-storage, retrieval-interface]
acquisition:
  alternatives: [mem0, postgres-memory, filesystem-memory]
verification:
  - store a random nonce
  - restart the agent
  - retrieve the nonce
  - delete it, confirm deletion
authority:
  read: autonomous
  write: autonomous
  delete: confirm
rollback:
  - disable the MCP server
  - restore the config backup
At that point the tech tree behaves less like a diagram and more like a package manager for agency.
Built: a capability may carry acquisition.alternatives, and ambit goal attaches them to each step. Alternatives, not one blessed answer, because the trade-off is rarely setup time: the hosted embedding API is three minutes against ten and costs money and a data boundary, and the plan says so.
The contract is built. contract.can lists the actions a capability confers, and each action is a node with its own authority: ambit authority version-control reports that reading the repository and committing may happen unattended and that pushing a branch and merging to the default branch may not.
Built: executable verification per contract action. A contract entry may be a name or { id, verify }, and ambit verify act:<capability>/<action> runs the action's own check against the action node. Reading a repository is a weaker claim than having read a particular repository, and the two now carry separate evidence. ambit verify with no argument runs every declared node check and every action check; ambit verify <capability> still answers "no check declared" instead of erroring.
#4. Detection becomes verification — built, and gates
Today detection is regex against discovered configuration. That is a reasonable bootstrap, and it is honest about what it proves, which is that something named Ollama exists. It does not prove an agent can use Ollama to finish a task.
Each capability gets a lifecycle:
UNKNOWN → DETECTED → CONFIGURED → VERIFIED → RELIABLE → DEGRADED → BROKEN
with verification that executes:
Local Tool Calling
  detected:  a Qwen model is configured
  verified:  model emitted a tool schema, the tool ran,
             the result returned, the model used it
  reliable:  47/50 fixture tasks passed
Built: nodes may declare a read-only verify command; ambit verify runs it and records the outcome in session_learning. ambit verify <id> --history returns the history, and reliability is reported as passes over runs: one success is a weaker claim than forty-seven of fifty.
Checks execute, so a curated check lives in this repository, a skill's is registered with the skill (§12.5), and none runs until asked. Nothing verifies on seed. Most capabilities, and most MCP servers a person adds, declare no check at all.
What the checks decide is narrow on purpose. A capability is reached when a config provides it and its required prerequisites are reached, and verified when it is reached and its declared check last passed. One that has never been checked is reached and unverified, and still counts everywhere. A failing check takes a capability out of every plan, permission and ranking. Checks only ever take away; permission is a separate layer (§9), so the chain is installed ≠ working ≠ authorized.
The lifecycle is built and stored. capabilities.lifecycle holds unknown, detected, configured, verified, reliable, degraded or broken, derived on seed and after each verification from providers and recorded evidence — five runs with the last five passing is reliable, one passing run is verified, a check whose last run failed is broken, and a pass after a failure is degraded, which reads as recovering. The latest check decides availability: only broken is left out, and a recovering capability is usable and counted as unverified until its window is clean.
state is untouched beside it, deliberately: state is what every frontier snapshot records, so repurposing it would break the ledger to answer a question the ledger does not ask. A capability whose check fails is therefore broken and still in the frontier — reachable and working are different columns, and collapsing them would lose the distinction this section exists to make.
Promotion on evidence is built, at the grain where it changes what happens, and §12.6 describes it. A person sets a threshold on a grant once, such as stop asking me about this after three passing checks in thirty days, and the evidence decides when it takes effect. A single failing check afterwards puts the grant back, and that half needs nobody. The lifecycle itself still only moves on the evidence of its own check, which is what it should do.
#5. Goal → capability delta — partly built
The headline capability of the mature system. Given a goal, compute the gap and the routes across it:
plan("maintain homelab unattended")

  have    ✓ tailscale  ✓ docker  ✓ proxmox  ✓ shell
          ✓ notifications  ✓ scheduling
  missing ○ service health observation   ○ bounded restart authority
          ○ credential broker            ○ rollback snapshots
          ○ post-action verification     ○ escalation policy

  A  broad authority          45 min   risk high
  B  capability-scoped MCP      2 hr   risk low    unlocks +7
  C  kubernetes migration      14 hr   risk med    unlocks +19,
                                                   regret-if-abandoned high
Built for the narrow case: ambit goal <capability> walks hard prerequisites depth-first and returns them in the order they must be closed, with an estimate.
ambit goal offline-capable
  goal: Offline Capable · steps: 2 · estimated setup: 25m
  1. Embeddings        10m
  2. Local Embeddings  15m
The route in is built. The curated tree carries a goal vocabulary, which is the intent-side mirror of detect. Where detect matches config ids and says "a git MCP named X is Version Control", goal says "a person wanting to deploy without me means Continuous Delivery and Scheduled Work". ambit goal <sentence> ranks every capability whose words appear in the sentence, each with its plan delta, so a free-form goal becomes a shortlist of concrete plans instead of an error:
ambit goal "maintain the homelab unattended"
  recommended: Scheduled Work
  Scheduled Work       unattended          → steps 3 · 50m
  Observability        maintain           → steps 1 · 30m
  Self-Hosted Stack    homelab            → steps 2 · 2.5h
A sentence the vocabulary cannot place has one more route: ambit goal --judge (or ambit_goal with judge: true) asks a judgment model on this machine which node it means, as a Choice over the tree, and returns the likeliest with its probability. With no judge answering, an embedding model on this machine returns the nearest nodes in meaning, each with its similarity. It suggests and writes nothing.
ambit goal <capability> --paths compares the alternative ways to close the gap, deriving risk from what the alternatives themselves carry (hosted moves data off the machine, recurring adds a bill, a step without a config patch cannot be undone by §10) and folding identical paths together so the list is of choices, not accidents:
ambit goal web-research --paths
  5m   risk low   local   none   reversible
Web Research has one authored alternative, so the comparison is one line, and every column in it is derived from what that alternative carries, not authored beside it.
#6. Failure becomes an input — built
session_learning is more important than it currently looks. Every failed task should be classified: was it reasoning, missing knowledge, a missing tool, a missing permission, weak infrastructure, or an unreliable capability?
Built. ambit record <capability> records that work was blocked by something missing, and ambit status reports which deficits recur. One is bad luck, three is a structural deficit and the verdict says so. Both are exposed over MCP as ambit_blocked and ambit_deficits, since an agent hitting the same wall is exactly who should record it.
Classification is built. ambit record <capability> <class> ["what you were trying to do"] records why work was blocked (reasoning, knowledge, tool, permission, infrastructure, or reliability) and ambit status reports the causes beside the count, so a capability blocked four times as a missing tool and once as a missing permission reads as one structural deficit and one incident instead of five of a kind. ambit_blocked accepts the same classification over MCP.
Inference is built, from the signals and not from the prose, and §12.2 describes it. A runtime already states that a command was not found, that permission was denied, that a host was unreachable, that an MCP call returned an error kind, and the runtime's bridge (the OpenCode plugin or the Claude Code plugin's hooks) hands those over for classification, so the ledger fills from work instead of from someone remembering to record it. A failure whose shape says nothing is left unclassified, never guessed at, and one that cannot be attributed to a capability is kept anyway, since "this keeps failing and the model cannot name it" is a finding about the model.
The tree already tells you to write a SKILL.md for anything you explain more than twice. Generalized, that rule is the governing principle of the whole project:
Repeated friction should become infrastructure.
#7. The ledger — shipped
Built. frontier_snapshots records every capability's state on each seed, written only when the state differs from the previous observation, so the table logs changes and not runs. ambit history lists the observations, and ambit history since <when> [<until>] compares two, or one and now. The map's timeline draws the same observations, one per second the ledger took a snapshot in, from /api/frontier.
The entry that justified the table works:
ambit history since
  frontier then: 13
  frontier now:  19
  gained:    Embeddings · Local Embeddings · nomic-embed-text
  emergent:  Model Routing · Offline Capable · Subagents
emergent is the column a per-component changelog cannot produce: those three became reachable although nothing providing them was added. Offline Capable was already provided by an agent that did not change — it flipped because its prerequisites were satisfied elsewhere. One embedding model was added; six capabilities moved.
Classification compares against the ids recorded in the snapshot and never against timestamps, which resolve only to the second.
ambit history also distinguishes a fourth thing, which is vocabulary. A node the past observation never saw, everything supplying which the past observation did see, is Ambit having started to model a part of the system, not the system having changed: the release that introduced action nodes, or a capability added to the curated tree that your existing tools already provide. Those are described and not counted, so frontier_now stays on the same basis as frontier_then and upgrading Ambit never reads as capabilities gained.
Use is written to the session history. The OpenCode telemetry plugin and the stdin bridge (scripts/adapters/telemetry.ts) post to /api/telemetry, the Claude Code plugin's hooks spool tool runs, failures and asks, the control plane opens a run for each call routed through it, an agent records its own work over MCP, and ambit incidents opens a run for each declared service that does not answer. Other runtimes have no bridge yet. Each capability a run exercised is recorded, and a successful use counts as evidence (§13.2), but a use carries no object, so which repository was committed to is not a question the ledger can answer yet (§13.9). It also records demonstrated reliability beside reach: each snapshot carries a verified count and an id→lifecycle map, so ambit history reports a capability that stopped working as diminished (with reason: verification failing) while frontier_now stays flat — the check started failing, nothing was removed.
#7b. Affordance domains — built, derived
ambit graph affordances (and ambit_affordances over MCP) derives each capability's domain from its structure instead of from a keyword. The theory carries the argument for reading them that way, and names the environment term the derivation still has no representation for.
| Domain | Derived when | Why that is the test |
|---|---|---|
| institutional | an actor authorizes it | an authority holder must exist for it to be acquirable |
| economic | its acquisition carries a recurring cost | a budget and a counterparty are implied |
| cognitive | a person supplies it | human cognition is necessary to produce the action, which is the human-composed case; approval is the human-gated case, and §9 covers it |
| physical | a provider runs on a device | a robot arm and a neural decoder seed and render alongside MCP servers, where before anything acting on the world collapsed into meta |
| machine-composed-human | a person and a machine both supply it | the affordance is in the loop and in neither half, which is the theory's BCI case given a structural home |
A capability can satisfy several, and all of them are named: one that an actor authorizes and whose acquisition carries a recurring cost is institutional and economic.
#8. A runtime adapter layer — partly built
Do not model "Claude has tool X, Hermes has tool Y". Model what each runtime provides, and let the graph decide which runtime can execute which step:
             send-email
          ╱      │       ╲
    Claude     Hermes    OpenCode
    connector  SMTP      MCP server
The point is durability. You stop maintaining a setup for one assistant and start maintaining a capability fabric that different intelligences attach to, which matters more each time the model landscape shifts.
scripts/adapters/hermes.ts reads a Hermes installation and contributes its capabilities to the same graph, with AMBIT_RUNTIME attributing them to a runtime node. Ids are deliberately not namespaced: a git MCP under either runtime is one capability with two providers, and the runtime edges keep that legible.
What building it surfaced:
- Hermes exposes authority as data (
approvals.mode,approvals.cron_mode), so §9 has a real source of truth to read instead of a schema to invent. - Detection was tuned to one runtime's naming. Hermes names a model
Jan-v1-4B-Q4_K_Mwhere OpenCode names the runtimeollama; quantization suffixes are now a local-weights signal. - No runtime publishes a machine-readable capability surface. Reading another tool's private files works and is not the right contract. The durable version is an export the runtime owns — and the export now exists:
ambit graph surfaceemits the graph's whole vocabulary (nodes by kind, edges by meaning, authority grants) in a schema-versioned manifest, andscripts/adapters/surface.tsconsumes one, so a runtime that publishes a surface is read directly and file-parsing is only the fallback. The round-trip works, which is how the contract gets exercised before any other runtime adopts it. - Both adapters hand the authority they read to the engine in the same fragment they hand over their MCP servers, so what a runtime permits reaches the graph and can narrow what the model says an action is like in general.
- The editor is an assistant runtime too. Cline, Roo Code, Continue.dev, and Zed each maintain assistant sessions and tool registries. Ambit reads their configurations automatically in
src/engine/mcp-clients.ts, unifying standalone agents and editor sidecars on one graph. What remains is a native IDE sidebar extension (VS Code, Cursor) embedding the AG-UI event stream to eliminate switching to the browser, while respecting the loopback boundary: the extension reads the graph over HTTP and requests approvals through the authenticated CLI.
#9. Authority as a first-class edge — built, and mediates one thing
The server already refuses to create MCP entries because those entries contain commands that get executed, binds to loopback, and rejects foreign origins. That boundary should be generalized, never weakened.
Per capability:
OBSERVE  autonomous     EXECUTE   conditional
PLAN     autonomous     VERIFY    autonomous
SIMULATE autonomous     ESCALATE  autonomous

docker-container-management
  inspect: autonomous   recreate: confirm
  restart: autonomous   delete:   confirm
                        change_mount: forbidden
This is not guardrails instead of capability. Granular, legible authority is what makes it safe to grant a much larger total action surface — the agent can be given more precisely because the limits are explicit.
Built. Authority is a table, not a blob on a node: each grant records its mode, its source, its holder and its scope. ambit authority splits reached capabilities into what may run unattended and what may not — Shell Execution is reached everywhere and still gated; Secret Management is forbidden outright.
Also built: authority derived from the runtime that would execute the step. Hermes states approvals.mode and approvals.cron_mode, Claude Code states permissions.defaultMode, and both adapters now pass them through. A runtime's grant is held against the runtime node and resolved through what it contributes, so a capability added in a later run cannot miss a grant recorded in an earlier one. Where the model and the runtime disagree the narrower wins and the report names which source narrowed it, since that is the half worth knowing. An unrecognized approval setting becomes confirm, never autonomous: guessing permissively would describe a system as freer to act than the runtime in front of it permits.
And the granularity the section asked for. The docker-container-management sketch above (inspect autonomous, recreate confirm, change_mount forbidden) is expressible now that a capability's contract actions are nodes with their own authority.
Scope decides, and is not only reported (§13.3). It decides by two rules, in order: a forbidden grant wins outright at any specificity, and among the rest the most specific covering scope governs, ties going to the narrower mode. That is what makes yes, on staging expressible — under narrowest-wins alone, a grant saying "autonomous on staging" could never beat the standing "confirm everywhere", so the trade of a smaller blast radius for unattended operation bought nothing and nobody offered it.
Mediating, now, in one place that matters. A grant holds only while what it rests on still works: canExecute reads the hard prerequisites of the capability being acted on, and an unattended grant standing over a failing one returns CONFIRM instead of ALLOW, so a grant never stays autonomous while its foundation is gone.
Three properties of how it does it. The stored grant is never rewritten: what a person declared stays declared, and the narrowing is a property of the decision, so nothing has to remember to put it back when the check passes again. It needs no recorder to have run first, because a gate that depended on a background job would be advisory again. And a declared sandbox is exempt, since consequences are contained there and acting on a broken foundation somewhere that does not matter is how the evidence to fix it gets gathered.
What that costs the caller is stated back to them: the decision carries narrowed_by, naming the capability and the lifecycle that took the grant down.
Where it is enforced. Every surface that says what may be done asks canExecute, and three places act on the answer: ambit apply, always; the control plane interceptor, when execution is routed through it (§15; its executor today is a fixture); and the Claude Code ambit gate hook, an opt-in plugin that can only deny or ask. Anywhere else the answer is read and not obeyed, so a runtime that goes through none of the three is unaffected by any grant.
#9b. The record it writes: STD-07 — shipped
§9 makes the gate mediate. ambit delegation writes the account of it as STD-07, the Revisable Delegation Record, which is a shape something other than Ambit can read. That is separate work from the enforcement and deliberately downstream of it.
ambit delegation --record writes four kinds for every grant currently narrowed by a failing foundation: a capability record for the thing that broke, an authorization record for the grant, carrying in depends_on what it rests on and in invalidated_by what would end it, a discrepancy for the divergence, and a revision superseding the authorization. Verification calls it too, since that is the moment evidence changes.
The records are append-only and hash-chained. The hash is sha256 over the record without its integrity block, with keys sorted, and each row carries the hash of the one before, so an edited or deleted record is detectable. ambit delegation verify recomputes the chain. ambit delegation --export emits newline-delimited JSON.
Conformance is declared as level 2, for those kinds and the objection a person writes with ambit delegation object; a stream holding an objection and its answer measures at level 3. action and outcome are deliberately not emitted: the environment adapter is simulated, so an action record from here would attest to a fixture. The manifest in server.json says so, because the standard's own adoption note is that declaring a level honestly is conformance and claiming one the log does not earn is not.
A record format with publishers and no readers is a documentation format, so the reading half is built too. The Audit view merges the records into the trail beside acts, proposals and runs (G4). ambit delegation ingest <file>, or a source declared once and read on every full ambit verify, admits another system's discrepancy records about capabilities this graph knows, as evidence attributed to the sender. A foreign record moves no lifecycle, so no remote system can narrow a grant here by sending a file, and a foreign authorization is not read, since importing one would import authority. The deep dive has the detail.
#10. A second-generation MCP — partly built
The first MCP tools were analytical: they answered questions about the graph. The second generation exposes the lifecycle of a change, and each stage sits on one side of a line:
| Stage | Over MCP | In the terminal only |
|---|---|---|
| Ask before acting | ambit_can, ambit_actions |
|
| Plan | ambit_goal, ambit_plan, ambit_paths |
|
| Simulate | ambit_simulate |
|
| Propose | ambit_propose, ambit_proposals |
|
| Approve | none, by design | ambit approve |
| Apply, roll back | none | ambit apply, ambit rollback |
| Verify | ambit_verify |
|
| Record what happened | ambit_blocked, ambit_record_failure, ambit_work_event |
|
| Choose what comes next | ambit_next, ambit_opportunities |
Simulation matters as much as planning: showing the graph as it would be, before anything changes, is what makes approval meaningful and not ceremonial.
Built, the two safe stages. ambit goal <capability> --simulate computes the frontier as it would be, against a copy of the state; its useful output is not the acquisition but what comes with it. That is a capability already provided and held back only by the prerequisite the change satisfies. On this machine, acquiring a vector store moves the frontier by two, because Retrieval is already supplied by an agent and waiting.
ambit propose <capability> [n] drafts a reviewable acquisition: ordered steps, the alternative chosen and its cost and privacy consequences, the simulated result, stored in a proposals table. Choosing the hosted alternatives for Retrieval takes it from 25 minutes to 13, at a per-token bill and a data boundary. The trade-off is stated, not implied.
Every step carries an inverse, or it carries null. That is the gate, not an omission: no step may execute without one.
Also built, both sides of the threshold except the act itself. Alternatives whose acquisition genuinely is a config change carry a declarative config_patch, and inverseOf derives the undo from it — removing what it adds, or restoring what it overwrites when the key already exists. Anything needing an installer or a running service gets no inverse, and null is a refusal, not a gap: a proposal is applicable only when every step has one.
ambit approve <proposal> --by=<person> records approval as evidence against a human: node, so the ledger can later answer who authorized an expansion of the frontier. It refuses a name that is not a person in the graph, because an approval has to come from someone accountable, and refuses to approve twice. It is deliberately CLI-only and not exposed over MCP: an agent may draft and preview, but approval is the human's act and should not be reachable by the thing being approved.
Built, with the two decisions made explicitly.
Scope is configuration, structurally. A step carries a declarative patch or it carries nothing; there is no field that holds a command, so no data file in this repository can cause something to be executed. That is the shape addMcp over HTTP had, and refusing it permanently is worth more than gating it.
Approval stays in the terminal. The write path is off the network entirely. A browser-reachable apply would reopen the surface this project spent its early work closing; the visualizer can display proposals without being able to authorize them.
ambit apply refuses in this order: unknown proposal, already applied, not approved by a person, any step without an inverse, any step that is not a configuration change. It backs the file up before the first byte changes, writes, records the act against the approver, then verifies the goal — and if verification fails, rolls back automatically and reports the change as reversed, not as a success.
ambit rollback uses the stored inverse instead of the backup, because the inverse describes only what the proposal changed; restoring a whole backup would discard anything edited since.
An apply re-seeds, so the graph reflects the change immediately instead of on the next manual seed — both on a successful apply and on the rollback that follows a failed verification, which is the "reversed" half of the same guarantee. The order that matters is enforced: the inverse is computed and stored before a step runs, verification promotes state only on evidence, and a failed apply runs its inverse automatically.
Built: the MCP column above, with ambit_evidence, ambit_authority, ambit_since, ambit_ledger and ambit_deficits beside it, so an agent can ask whether a capability is real, whether it may act and what is missing, and record being blocked, as a person can from the terminal. ambit_actions is the one an agent should reach for before acting: ambit_authority answers at the capability grain, and permission is per action.
Built, the contract around those tools. A client is told what Ambit is at connect (instructions, which carry the ask-before-acting habit), the protocol version is negotiated, and each tool says whether it changes anything, and a test holds that claim against the database. A call is checked against the tool's schema, and a failed one comes back as isError with what to send instead, by the rule the CLI's exit code follows. resolveCapability is the one place that decides which node an id means, and it never guesses. ambit mcp --profile=agent lists only the tools a working agent uses, and a test holds each listing to a byte budget. How a call is answered has the detail. Still open: an outputSchema for each answer, which structuredContent carries as data and nothing yet describes, and JSON-RPC batching, which no stdio client sends and which is why 2025-03-26 is not claimed.
What remains is transport variety, execution sandboxing, and an authenticated CLI installer. Stdio processes launched on the local host are only one deployment model; MCP servers now run over HTTP/SSE and WebSockets across private containers and cloud backends. The reader and proxy must attach to remote endpoints without assuming a local PID. Untrusted community servers also need isolation: executing stdio tools inside container or WebAssembly sandboxes bounds their filesystem reach. And while entry creation over HTTP is permanently rejected, an authenticated CLI installer (ambit install <server>) bridges discovery and configuration without compromising the loopback boundary.
#11. The visualizer becomes a negotiating surface — built and shipping
Ambit implements the state and run subset of AG-UI, the Agent-User Interaction protocol: /api/events streams RunStarted, a StateSnapshot on connect, and — when the graph changes underneath the view — a StateDelta of RFC 6902 patches plus a TextMessageChunk narrating the change. The client reloads when the graph changes. The immediate benefit is a view that does not go stale when a seed or an adapter rewrites the graph; the durable one is that the transport an agent would use to propose a change, and a human to approve it, already speaks a standard vocabulary and not one invented here.
StateDelta is the protocol's reason for existing: a patch is smaller than a snapshot, and a client that kept the connect snapshot can apply it. The delta is emitted for every change after the initial snapshot, so the transport is honest about what changed instead of resending the whole graph.
The visual negotiating surface is shipping:
- Simulation on the canvas. Simulate an outage dims the map and draws the multi-hop cascade in red with a count of what stops working; Simulate unlocking this rings what becomes reachable in blue. Neither writes anything.
- Approval in one click. The Proposals panel shows what an agent drafted, whether every step has an inverse, and signs a receipt; applying stays a command the person runs.
- Three lenses, switched on the map itself: Standard; Attention (nodes shaded by how often a person had to step in), offered once the ledger has recorded any; and Authority (each reached node by what it may do without asking, with "no grant yet" apart from a refusal). Shared credentials are not a lens: they are declared, and the engine reports them (
ambit credentials). - A proposal read as a plan. Above its steps the panel tallies them, marks any with no inverse, and says whether
ambit applywould refuse the draft, before anyone approves it. - A queue. When two or more drafts wait, the panel lists them with a box each and decides the ticked ones together. Each is signed on its own, bound to the hash the page showed, and refused alone if the row changed since. Drafts only, at most fifty, and always as the web actor.
- The trail. An Audit view lists who approved what and what ran, one line per event, newest first, from four sources under one limit, with a query bar (
actor:,action:,target:). - My Setup says how each check went. Each row carries a strip of the last fourteen runs of the checks behind it, and a tool server's switch writes
enabledto the config it came from, keeping the file it replaces as<config>.bak.
Not implemented: tool calls and reasoning events. Ambit does not execute agent steps — it models the environment those steps would run in — so fabricating a tool-call or reasoning stream would be noise in the protocol's own vocabulary. Calling Ambit "AG-UI compatible" would still overstate it; it implements the state and run subset deliberately.
A2UI was evaluated and rejected. It is a generative UI specification: agents describe components and the front end renders them. Ambit's interface is a designed visual grammar — era columns, three states, dependency edges, a legend — and its legibility is the product. Letting an agent improvise components would replace a representation that was reasoned about with one that is generated per response. A2UI suits surfaces where the agent's output shape is unknown in advance; here it is known and deliberate.
The map has the ergonomics a large setup needs. When it is bigger than the window, a minimap shows all of it and the part on screen. A focus mode, opted into from a node's panel, keeps only that node's neighborhood, out to a chosen number of hops in a chosen direction. An era opens as a ladder of what is reached, next and blocked. And a timeline under the map redraws it as any recorded observation of the frontier left it, so an operator can watch the frontier expand over time. The interface specs record what each does and where it departs from the first draft. The timeline scrubs and does not play: nothing advances it without a person. ambit share writes the map as a standalone HTML snapshot, and the saved image is a card of the map's finding, not the map.
#12. The long-running agent — built
Everything above assumes someone asks. A long-running agent — one that works with the same person across weeks, on more than one machine, and wants to become more capable — does not ask. It hits a missing binary mid-task, works around it, and hits it again next week. Ambit's thesis is exactly that agent's loop: friction, deficit, acquisition with approval, verification, a larger action space. What was missing was the plumbing that puts Ambit in front of the agent at the moment friction happens, and that turns growth into something the person can grant instead of something the agent has to request each time.
Each part is built and tested in src/engine/agent-loop.test.ts, src/mcp/server.test.ts and src/engine/dispatch.test.ts, and the deep dive is the reference. What each one decided, and why:
- The briefing is an MCP resource,
ambit://briefing, because a resource is what a runtime reads at connect and a tool has to be thought of first. Prose with ids, capped near 1,200 tokens by trimming whole lines from the bottom, since the order is the order of usefulness. Reading it applies any threshold whose evidence now supports it: asking what the environment is like is the right moment for an authorized promotion to take effect. - Passive deficit capture classifies failures the runtime already reported (exit codes, error kinds, messages) in the engine, never in the bridge, because a bridge that judged what counts as a permission error would be a second copy of the rule. A failure whose shape says nothing stays unclassified. Every signal is counted; the attributable ones also become deficits.
- One question before acting.
ambit_cananswersyes,askornoin one round trip from three indexed reads, and anofiles the deficit in the same call, so the habit costs one call and not two. The server also sends the habit as itsinstructionsat connect, so it no longer depends on the person having pasted the line into an agent's rules. - A curriculum.
ambit nextranks by observed blocks when the ledger has them and by leverage per hour of setup when it does not, and says which. It offers only what is one acquisition away; anything further is a project, andambit goalis where projects live. It answers instead of drafting proposals, because answering a question by writing three rows is how a table fills with documents nobody chose. - The agent's own growth. A skill the agent wrote goes on the map only with a read-only check that runs immediately, because an unverifiable claim of new capability is the exact failure this project exists to prevent, and worst coming from the agent whose reach it widens.
- Evidence to authority. A person sets a threshold once; the grant widens when the evidence arrives and narrows on one failing check with nobody asked. A
forbiddengrant takes no threshold, since that would be a mechanism for talking a system into what it was told not to do. Demotion compares row ids, not timestamps, for the reason §7 gives. - The digest is built into the briefing and not beside it: every briefing carries what changed since the last one, and the mark moves when it is read, not on a schedule.
- A ledger that travels.
ambit syncmoves the graph and the ledger as one file against an allow-list. Commands do not travel, because a command in a data file runs on whoever imports it; grants do not travel, because importing one would let a permissive machine widen a careful one by moving a file. - One line to install. An agent that decides Ambit would help should not need a checkout to act on it.
ambit-cliis on npm, sonpx ambit-cliruns it on a machine with Node and nothing else, andclaude mcp add ambit -- npx -y ambit-cli mcpregisters it with Claude Code.brew install zz-plant/tap/ambitis the same files: the release workflow writes the Homebrew formula from the npm tarball, built page included. Its npm and tap jobs publish only when the repository holds their tokens. - Out-of-band approval dispatch. When a long-running agent drafts a proposal while the operator is away from the machine, the loop stalls.
ambit dispatch <id>(orpropose --dispatch,approve --dispatch) pushes it to a Slack, Discord or Telegram webhook, an ntfy topic, or any JSON endpoint, chosen byAMBIT_APPROVAL_WEBHOOKor--to. A draft goes out with its goal, cost, what it unlocks, and theapprove/rejectcommands; an approved proposal goes out with its signed artifact, so what the phone shows is whatapplywill verify. The channel is one-way on purpose: no token in a chat message mints an approval, because a chat is not a machine that holds the key, and the reply comes back throughambit approvewhere it always did.
session starts → briefing (12.1) → agent asks before acting (12.3)
      ↑                                       │
      │                          no → deficit recorded (12.2)
      │                                       │
      │                          recurs → next (12.4) → propose → approve (12.10)
      │                                       │
      │                          acquire → verify → registered (12.5)
      │                                       │
      │                          evidence accrues → authority widens (12.6)
      │                                       │
      └────── digest says what changed (12.7), on every machine (12.8)
#13. Expanding the ambit — built
§12 puts Ambit in front of the agent at the moment friction happens. It does not, on its own, make anything grow: an agent can notice a gap, name it, ask about it and be told no, and the environment is exactly as capable at the end of that as at the start. What decides whether the loop widens is mostly not in the agent. Every acquisition costs one human interruption, so the growth rate is proposals multiplied by the odds of a yes, divided by what saying yes costs — and only the last term is easy to change. The other half is evidence: autonomy earned only from self-tests the agent triggers is synthetic, when the ledger already records the capability doing the actual job.
Built, with acceptance tests in src/engine/expansion.test.ts, src/engine/ttl-authority.test.ts and src/engine/techtree-overlay.test.ts:
- The graph asks for the threshold.
ambit authority promotewith no arguments names grants confirmed by hand three or more times with clean evidence and no threshold, each with the command that would end the asking. It suggests and never sets; an agent that could set its own threshold would be granting itself authority through a side door. - Real work counts as evidence — the capability exercised inside a run that achieved its outcome is counted beside a passing check. Only checks count against: attributing a failed run's outcome to everything it touched would demote whatever a bad afternoon went near. Scoped thresholds count checks only, because use carries no object.
- Scope traded for mode.
--scopewrites a new grant for one target and leaves the standing one untouched. §9's resolution rule is what makes it mean something. - Somewhere to practice. A declared sandbox relaxes confirmation inside itself and never a refusal, since rehearsing a forbidden action would be a way round it. It is where a scoped threshold gets met cheaply: practice in staging, earn staging.
- A ceiling instead of a gate. A standing budget is a ceiling on spend, and a spend past it is refused until the period turns over, with nobody having to notice. The refusal reaches a caller that states its spend (
ambit can --spend, or the MCP tool'sspendCents);applyand the control plane state none, so a spent budget changes nothing on those paths. It bounds a grant and does not widen one: within the ceiling the grant's own mode still decides, so aconfirmaction still asks, and the delegation this section describes is an autonomous grant with a budget beside it. An elapsed period reads as spent-nothing without writing, because a decision API that wrote to the database to answer a question would be a strange thing to put in front of every action. - Reversibility as the growth lever.
applyrefuses any step without a computed inverse, and read backwards that refusal is the list of what the agent can never do for itself.ambit reversiblepublishes both halves, separating "the recipes exist and none is a config change" from "no recipe at all". - Learning from the refusals. A graph that records only approvals learns what a yes looks like and never a no, so
ambit rejectrecords the other half; a trait needs three decisions before it counts and one that went both ways reads as contested, not settled by majority. - The cost of a yes. Pending drafts and the approval push carry the decision (goal, cost, bill, what it unlocks) instead of announcing that one exists, and
approvetakes several ids and one name. Each still gets its own signed artifact, and apply still runs one at a time. - Actions carry objects, in the slice that pays first: authority and evidence can refer to a target,
verify --targetfiles the result against it, andambit objectsreports what may be done to one thing on what evidence. The era tree is untouched; what this establishes is that committing to one repository forty times proves nothing about the next one, and the graph can now say so. - Time-bounded elevation. A standing grant alone is permanent confirmation or permanent autonomy, so an operator pairing closely with an agent for an afternoon would have to confirm every command or grant autonomy for good.
ambit authority grant <cap> autonomous --ttl=30mrelaxes confirmation for the window and no longer. Expiry is read at decision time and never written:canExecuteskips a grant whoseexpires_athas passed and lets whatever still covers decide, so a standing confirm is confirm again and nothing at all is a refusal again. An expired row that still bought confirmation would be a permanent widening by way of a grant that had ended. The expired elevation is named innarrowed_by, and the row stays as the record of what was granted and when it ended. A forbidden grant takes no TTL, for the reason a threshold does not. - Scoped tech tree overlays. The curated tree is general software development; a biotech or robotics team, or a company with private infrastructure, has capabilities it cannot name there.
.ambit/techtree.jsonin the working directory (orAMBIT_OVERLAY_TECHTREE) is merged over the curated tree before seeding: a new id is a new node with its contract and prerequisites, an existing id extends the curated node's detection and requirements, andoverride: truereplaces it, except its authority: an overlay narrows a curated mode and never widens one, and a node only the overlay names asks first at most. The overlay is data like the tree it extends, so nothing in it can name a command.
#14. The economic half — partly built
The loop in the argument is the graph half, and it is built. The first turn of the loop that pays for it is built too:
real work happens → the session history observes (runs, events, interventions,
consumption) → attention prices the human burden → opportunities ranks the
durable fixes → propose carries the observed case → the approval broker mints
a signed, expiring artifact → apply enforces canExecute and verifies → roi
measures before/after and writes the observation back
What exists: the session history and its AG-UI ingestion, the attention report that never flags judgment, the economic model (dollars declare, cents store), the opportunity engine ranked by attention/cash/roi/reliability/frontier, economic proposals, the signed approval broker with browser approval, the capital allocator (opportunities --budget N), the acquisition catalog (the supply side for the demand the opportunity engine finds), realized ROI, and a federation skeleton of signed summaries.
The loop page draws each standing budget's ceiling with a tick for where the period lands at its pace so far (L2), and says what each opportunity's capability needs and what is already here (S4).
Attribution must reach the capability grain. Knowing total model spend does not tell an engineering lead whether Web Research or Code Refactoring consumed the budget. Joining consumption ledger records with capability IDs breaks down token and dollar costs per node. The opportunity engine can then model provider arbitrage: comparing hosted API consumption against local hardware amortization to show when moving embeddings or code analysis to a local model pays for dedicated hardware.
#15. The control plane — built, against a simulated environment
The gate §9 describes stays a report until something consults it before acting. The interceptor is one of the three places that do: it sits in front of the tool call, and a call whose prerequisites are missing, whose foundation is failing, or whose caller is not permitted is refused with nothing on the machine changed.
The decision is real. It runs against the actual graph, through the same canExecute §9 describes and the same authority table, and it writes the same audit trail. The simulated environment behind it costs so little because the gate never learns what it is gating, which is also why replacing it is not a rewrite. The README describes what it does today.
Production enforcement requires intercepting live tool calls across real transports. Pre-execution dry-run blast radius simulation (simulate: true) computes the cascade over dependent capabilities and combos at risk before execution. During active incidents, an audited emergency override (break_glass: true with a mandatory reason) allows privileged execution while recording a break_glass work event that carries the reason.
#16. Federation, fleet governance, and team agency — partly built
Ambit starts on one developer's workstation. In an engineering organization, capabilities, credentials, and infrastructure are distributed across dozens of machines and engineers.
The loop in §14 extends to fleets:
local session history → signed summary export → team portfolio sync →
cross-machine capability routing → GitOps policy review → organizational frontier
What the team layer needs:
- Multi-tenant graph synchronization. Developers publish signed environment summaries (
ambit sync) to a shared organizational catalog. The team view aggregates shared infrastructure (homelabs, GPU clusters, shared databases) without sharing private credentials or local path configurations. - GitOps-driven governance. Capability contracts, authority defaults, and spending ceilings belong in version control. Teams manage capability policy via pull requests against a shared repository, letting code review govern which autonomous grants become organization defaults.
- Role-based delegation hierarchies. Distinct actors carry distinct trust profiles. Junior engineers and automated subagents inherit conservative confirm policies for production resources, while platform maintainers hold autonomous grants. The gate evaluates covering scopes across both user identity and agent role.
- Compliance and SIEM audit exports. Only the delegation records are hash-chained (§9b), so an export starts by deciding how far the chain reaches, and by recording the refusals and the actor the ledger does not hold today (G4). Formatting exports for SOC2 and ISO27001 compliance, and streaming audit events to corporate SIEM systems (Splunk, Elastic), turns agent oversight into verifiable enterprise infrastructure.
Two first slices are built: the Audit view (G4) and, on the Infra tab, what an agent may do on each machine (L3).
#17. Defined outcomes — proposed
Proposed and unbuilt. Extend §5's planning with evidence about complete workflows.
Can this setup achieve this outcome, on this target, within these limits?
Start with an authored staging-release rehearsal: publish a sample service, check its response, restore the previous version and check again. Record elapsed time and human attention. Production needs its own authority and evidence.
#Existing foundation and its limits
| Foundation | Gap |
|---|---|
goals.ts and plan/route.ts |
Route to curated capabilities; do not synthesize arbitrary workflows |
telemetry.ts |
Records outcomes and optional metrics without independently checking the claim |
assure/verify.ts and objects.ts |
--target labels evidence without changing the check command; the checker must establish the actual target |
ledger.ts |
Stores states, kinds and lifecycles, not past edges or grants; historical displays use current edges |
economics.ts, attention.ts and roi.ts |
Price declared costs and compare attention; do not establish revenue, profit or wealth |
#The proposed records
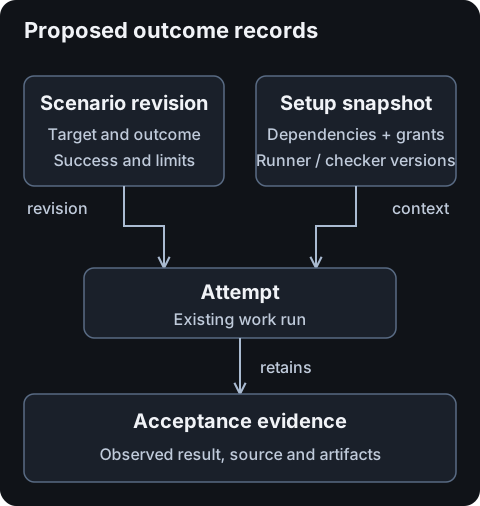
- Scenario revision: outcome, target, environment, prerequisites, human contributions, acceptance criteria, limits and recovery requirements.
- Attempt: reference to an existing work run, the scenario revision, relevant setup and grants at execution, and runner and checker versions. Preserve context without credentials; record unknowns.
- Acceptance evidence: expected and observed results, actual target, source, observation time and artifacts. Distinguish self-reports, external checks and rehearsals.
Reports keep modeled reach, authority, acceptance results, resource use and human participation separate. Changed conditions call for new evidence; historical results retain their original context.
#Demonstrations to build toward
- A setup change opens a route. Compare the same scenario before and after a change. Explain structural gains, missing authority and untested steps. Trust-boundary claims require a modeled path with applicable scopes.
- A workflow needs less personal attention. Test one bounded change and compare attention, workload, quality and recovery. Repetition alone does not justify removing judgment.
- An unchanged model achieves more in a changed environment. Hold the model, task suite, initial state, acceptance criteria and resource limits fixed. Vary selected affordances, repeat attempts and report actual consumption and added human work. Disclose uncontrolled differences.
The first slice should record attempts from an explicitly invoked external workflow or CI job. That executor supplies the actual authority checks and recovery handling. Ambit's read-only verification probes do not provide a contract for rehearsals that change a service.
Keep scenario records above the curated tree. Put reporting in the engine and projections in views.ts; customers and acceptance criteria do not add to capability counts.
#Evidence required before claiming completion
- Component checks can pass while scenario acceptance fails. Missing evidence is unknown, never success.
- Results identify the actual target and scenario revision, with relevant setup and grants preserved for comparison. Older snapshots cannot supply missing context retroactively.
- Definitions, imported results and successful rehearsals create no authority and cannot bypass refusals.
- Repeated runs report acceptance, costs and human participation for observed conditions. General success probabilities need separate calibration.
Other applications remain hypotheses. A paid service adds evidence about customer acceptance, cash movements and control over assets and returns. Less owner time alone establishes no increase in independence.
#18. Ontological rationalization — built and normalized
As Ambit evolved from an exploratory tech tree into a runtime gate and supervisory control plane, its vocabulary accumulated historical collisions and semantic inversions. This section unifies and formalizes the underlying ontology without breaking continuous stored ledger history.
#The decoupled assurance model: State × Assurance
Ambit's core claim is installed ≠ working ≠ authorized. The operational model reflects this by separating reachability from empirical evidence:
State (Reachability):   unconfigured ──► blocked ──► reached
                                                       │
Assurance (Evidence):   untested ◄─────────────────────┘
                          │
         ┌────────────────┴────────────────┐
         │ check passes                    │ check fails
         ▼                                 ▼
       proven ◄───────────────────────── failing
         │   ▲                             │
  5 pass │   │                             │ check passes
         ▼   │                             ▼
      reliable ─────────────────────── recovering
- State (
unconfigured,blocked,reached) answers whether the system is structurally wired to exercise a capability. It is continuous with the stored frontier snapshots. - Assurance (
untested,proven,reliable,recovering,failing) reflects the empirical health of the capability's declared checks. - Curing the
degradedinversion: Historically,degradedwas overloaded: wire fields used it for failing nodes, whilevocabulary.tsused it for recovering nodes. The model now standardizes onrecoveringfor nodes whose latest check passed after recent failures, whilefailingrepresents nodes whose latest check failed. - Binary check runs: In
session_learning, check runs record discrete outcomes:passedorfailed. The wordverifiedis preserved as an alias for backwards compatibility, but retired from row-level event semantics to prevent polysemic confusion with the assurance tierproven.
#Taxonomy normalization
The historical provider: and resource collisions are disambiguated into functional layers:
| Canonical Kind | Role | Description |
|---|---|---|
capability |
Coarse node | An outcome or composition the system can bring about. |
affordance |
Bound action | A concrete action bound to an object class (git:commit on repo). |
adapter |
Tool / driver | An MCP server, CLI script, or skill supplying affordances. |
upstream |
Remote service | Third-party APIs, inference endpoints, SaaS providers. |
model |
Model weights | Generative or predictive model checkpoints. |
substrate |
Compute host | Physical machines, local Docker daemons, execution environments. |
credential |
Identity token | Secret handles (never secrets) used to authenticate adapters. |
actor |
Principal | Human or team providing sovereign authority, budget, or oversight. |
Existing stored node ids (e.g. combo:version-control, provider:anthropic, model:claude-3-7-sonnet) remain byte-stable so the frontier ledger's multi-month diffs remain unbroken. kindOf normalizes both legacy and modern prefixes into canonical kinds.
#The Supervisory Ladder
Authority is unified from a coarse tri-state flag into a 6-rung progressive supervision model:
$$\text{Rung 0: Ungranted} ;\rightarrow; \text{Rung 1: Forbidden} ;\rightarrow; \text{Rung 2: Attended} ;\rightarrow; \text{Rung 3: Thresholded} ;\rightarrow; \text{Rung 4: Budgeted} ;\rightarrow; \text{Rung 5: Autonomous}$$
- Rung 0 (Ungranted): No grant declared. Default deny posture.
- Rung 1 (Forbidden): Explicit refusal. Break-glass cannot override.
- Rung 2 (Attended): Interactive human confirmation required on every invocation (
confirm). - Rung 3 (Thresholded): Progressive promotion on evidence: unattended execution conditional on $N$ consecutive passing checks; falls back to Attended on one failure.
- Rung 4 (Budgeted): Autonomous execution bounded by a standing financial or resource ceiling.
- Rung 5 (Autonomous): Full unattended execution backed by retrospective audit trails.
The runtime gate (ambit gate) resolves the active context against the ladder into instantaneous verdicts: ALLOW, CHALLENGE, or DENY.
#Human Agency Accounting: Compensatory Friction vs. Sovereign Discretion
The economic optimization loop distinguishes two fundamentally different forms of human participation:
$$\text{Labor} = \text{Compensatory Friction} ;\cup; \text{Sovereign Discretion}$$
- Compensatory Friction (formerly "middleware"): The human acting as a mechanical shim, router, manual verifier, or clipboard because tooling or sandboxes are missing. Recurring friction represents an actionable capability deficit to automate away ($\lambda \cdot \text{reusable_capability_created}$).
- Sovereign Discretion (formerly "keeper"): Essential human authority, ethical judgment, fiduciary risk assumption, and aesthetic intent. These are preserved by design and never counted as reducible friction.
#Sunset
Anything that told you something interesting about the graph without changing what you should do is not a first-class feature. The 3D visualizer, trend, recs, fork, insight, profile, prune, the setup/token budget, the consultant/snapshot/trending stores, and maturity_score as a headline are gone or demoted. What is left groups under five nouns (graph, plan, check, govern, report), and the deep dive enumerates it. What stays is what establishes truth, measures dependence, supports decisions, and governs change.
#The through-line: The Living Ambit
The table above collects what each section still lacks. Four core transitions run under all of it, carrying Ambit from a static graph into a living perimeter of agency:
From reporting to enforcement. Ambit can say what may be done, by whom, with what, on what evidence, and whether a grant covers a given target, and it narrows a grant when what it rests on fails. It stops something only in the three places §9 names, so a runtime that goes through none of them is unaffected by any of it. Closing this loop turns the graph from an external advisor into an active supervisor.
From abstract verbs to bound affordances. Every entry on the list the graph will eventually need (read repo A, write repo A, open PR, merge PR, deploy service B, restart container C, query database D read-only) is a verb bound to a noun, and the era tree still has only the verbs (§13.9). Once it carries objects, it stops being the ontology and becomes what it should be. That is a rollup over affordances, with Version Control derived from
{read, commit, push, merge}over the repositories that actually exist. An agent earns autonomy over repo A without acquiring blanket access to repo B.From static snapshots to ambient perimeter sensing. A capability graph that updates only when someone types a CLI command or boots an agent is an offline snapshot. In a production environment, the perimeter contracts and expands continuously: a local Docker daemon restarts, an upstream API token expires, a laptop switches networks, or GPU VRAM fills. Ambient sensing continuously validates health, reachability, and credential validity in the background. The moment a dependency fails, the perimeter contracts, preventing agents from falling into blind retry loops. The moment health clears, the capability returns.
From friction loops to reflexive boundary negotiation. When an agent hits an environmental barrier today, it either crashes or loops helplessly in its context window. In a reflexive system, friction is captured as a structured deficit. The agent inspects its own boundary, computes the capability delta, and drafts an approvable proposal complete with setup cost, reversibility recipes, and scoped authority limits. The human decides; the system verifies; the boundary expands. The agent never breaches its perimeter; it participates in negotiating it.
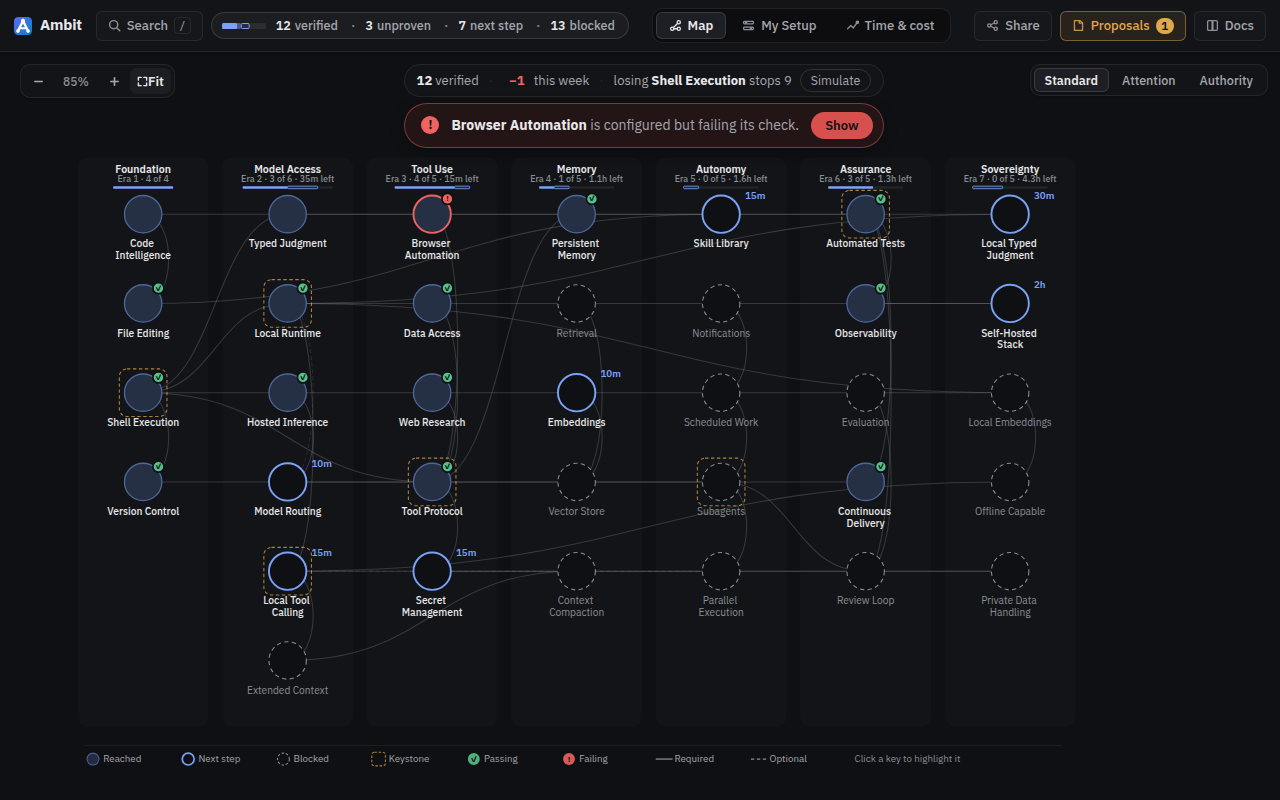
See what your own agents can reach
Ambit reads the MCP configs of Claude Code, Cursor, OpenCode and thirteen more agents into one local map: every server, which ones work, what one more step would open, and what breaks if a piece goes.
Open the live demoa sample setup in your browser, nothing to install
On your machine: npx ambit-cli, with Node 22.18 or newer on macOS or Linux.
MIT licensed · one local SQLite file, no telemetry · on npm and in the official MCP registry