#What stops when an MCP server or credential expires
An agent setup is a stack of dependencies nobody wrote down. A GitHub MCP server provides version control; version control is half of a review loop; the review loop is what lets an agent open a pull request on its own. When that server's token expires, the agent does not report a missing server. It reports that it cannot open a pull request, or it quietly does something else.
The question to answer before that happens is what would stop if this one server, model or credential expired or was removed. Security teams call that the blast radius.
#Three answers, not one
Losing a piece of the setup does one of three things to each capability that depended on it:
- It stops. Nothing else provides it, so it goes with the piece you removed. A server that is the only provider of something is a single point of failure.
- It weakens. Another server, model or tool still provides it, so it keeps working with one fewer way to do it. That is worth knowing and is not an outage.
- It was already broken. It was configured and failing before anything went down. Counting it as a loss would overstate the damage, and leaving it out would hide that it was never working.
A list of MCP servers cannot give any of these answers, because the dependency is not in any one config file. It is in how the servers, models, skills and commands combine.
#Finding them by hand
For a small setup, a table on paper is enough:
- Collect every MCP server from every config your runtimes read (where each runtime keeps it). For each, note the token or key it reads (usually named in its
envorheadersblock) and the host its URL or command reaches. - Write down what your agents rely on (opening a pull request, searching the web, querying a database), and next to each, every server, model or tool that can do it.
- Anything with one name next to it is a single point of failure.
- Anything whose names all read the same token variable, or all reach the same host, is one too, however many names it has. Revoke the token or lose the host and they go together.
- For the third answer, try each one. A server you have not seen work recently may already be broken.
This stops scaling at a few runtimes and a dozen servers, and it misses a capability one piece unlocks for another, which only exists in combination.
#Asking from the terminal
Ambit does the same for the whole setup. It reads every agent config on the machine into one graph and answers from it:
npx ambit-cli              # reads every agent config on this machine into the graph
npm install -g ambit-cli   # keeps the `ambit` command
ambit status               # what is failing, and what has a single provider
ambit impact mcp:github    # what stops, and what only weakens, if this one goes
ambit credentials          # what revoking each declared credential would end
ambit status lists the sole providers in the setup, which are the single points of failure, and lists what is already failing apart from them. ambit impact <id> takes any node, whether a server, a model, a credential or a capability, and splits what depends on it into what would stop and what would keep another provider.
Two of the answers need something from you first:
- Shared credentials are declared, never inferred. Ambit cannot see that three servers present one token until a
credentialsblock in the config names them (the shape). Until thenambit credentialssays none are declared, and three providers behind one token read as three providers. - "Already broken" needs a declared check. A capability counts as failing only when it declares a check and that check last failed (
ambit verifyruns them). Most MCP servers a person adds have none, so they read as reached and unverified: counted as working, never shown as broken.
#Seeing it on the map
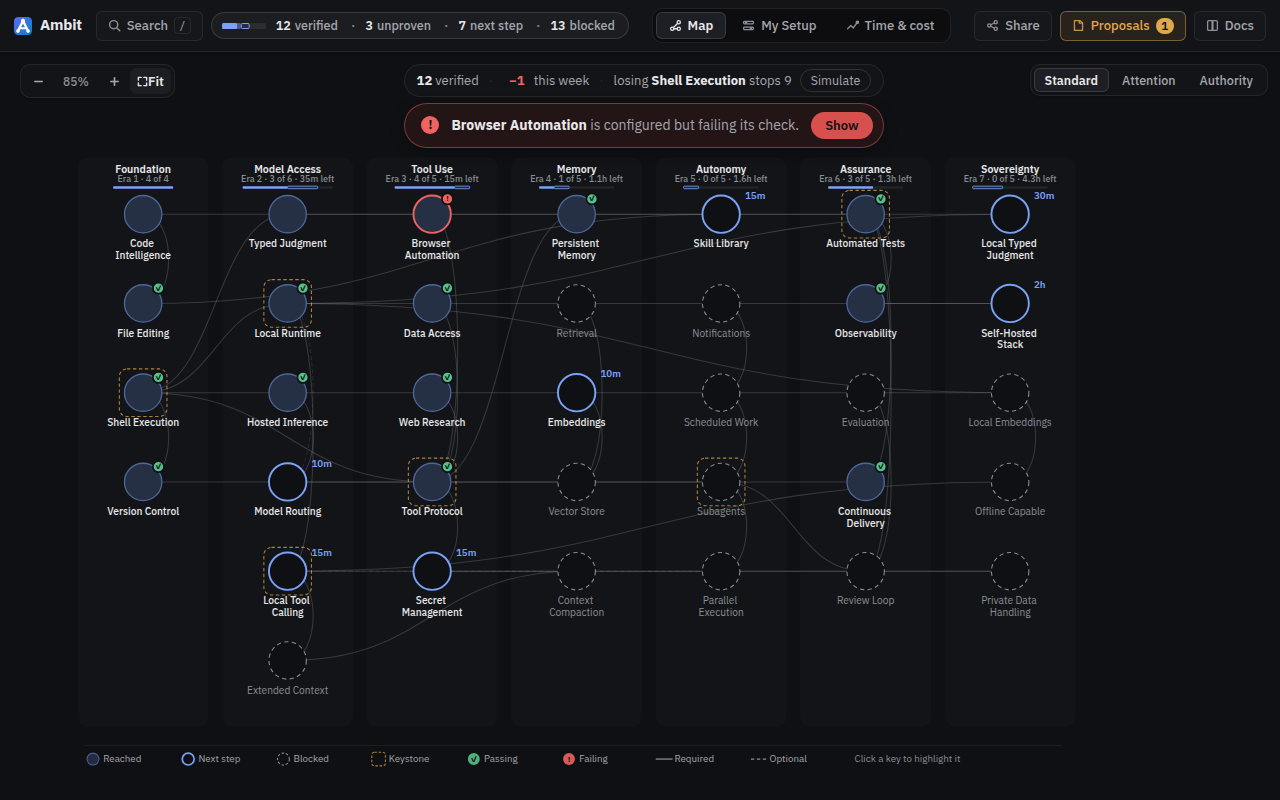
The hosted demo opens on the same answer for a sample setup: its MCP servers go down, and what stops turns red. Select any other node and press Simulate an outage to ask it of that one: what keeps another provider turns amber, and the node that went down is labelled with how many capabilities stop.
#Acting on the answer
Each answer has its own fix:
- For what stops, add a second provider: another server, model or tool that supplies the same capability.
ambit catalog <capability>lists the ways the tree knows to provide it, where it knows any. Once the new provider is in a config and seeded,ambit impacton the old one reports the capability as surviving. - For providers behind one token or host, declare the credential in a
credentialsblock so the sharing is counted, then give one of them its own key or a different host. - For what is already broken, fix or remove it, and declare a check where you can so the next failure shows up before an agent finds it.
Before removing a server or revoking a token on purpose, run ambit impact on it first. Its answer is as complete as the declarations behind it, so declare shared tokens and checks first.
Every new capability rests on pieces that already exist, so knowing which ones carry the most is the guardrail half of widening what a setup can do.
Related: where each AI agent keeps its MCP config and auditing which MCP servers a coding agent has.
See what your own agents can reach
Ambit reads the MCP configs of Claude Code, Cursor, OpenCode and thirteen more agents into one local map: every server, which ones work, what one more step would open, and what breaks if a piece goes.
Open the live demoa sample setup in your browser, nothing to install
On your machine: npx ambit-cli, with Node 22.18 or newer on macOS or Linux.
MIT licensed · one local SQLite file, no telemetry · on npm and in the official MCP registry